How to move large files over the network without suffering
Published on 2026-09-12 by frfrand
Por qué copiar 200 GB con el método equivocado tarda el triple, qué hace rsync que scp no puede, y cómo diagnosticar si el cuello está en el disco, la red o la CPU.
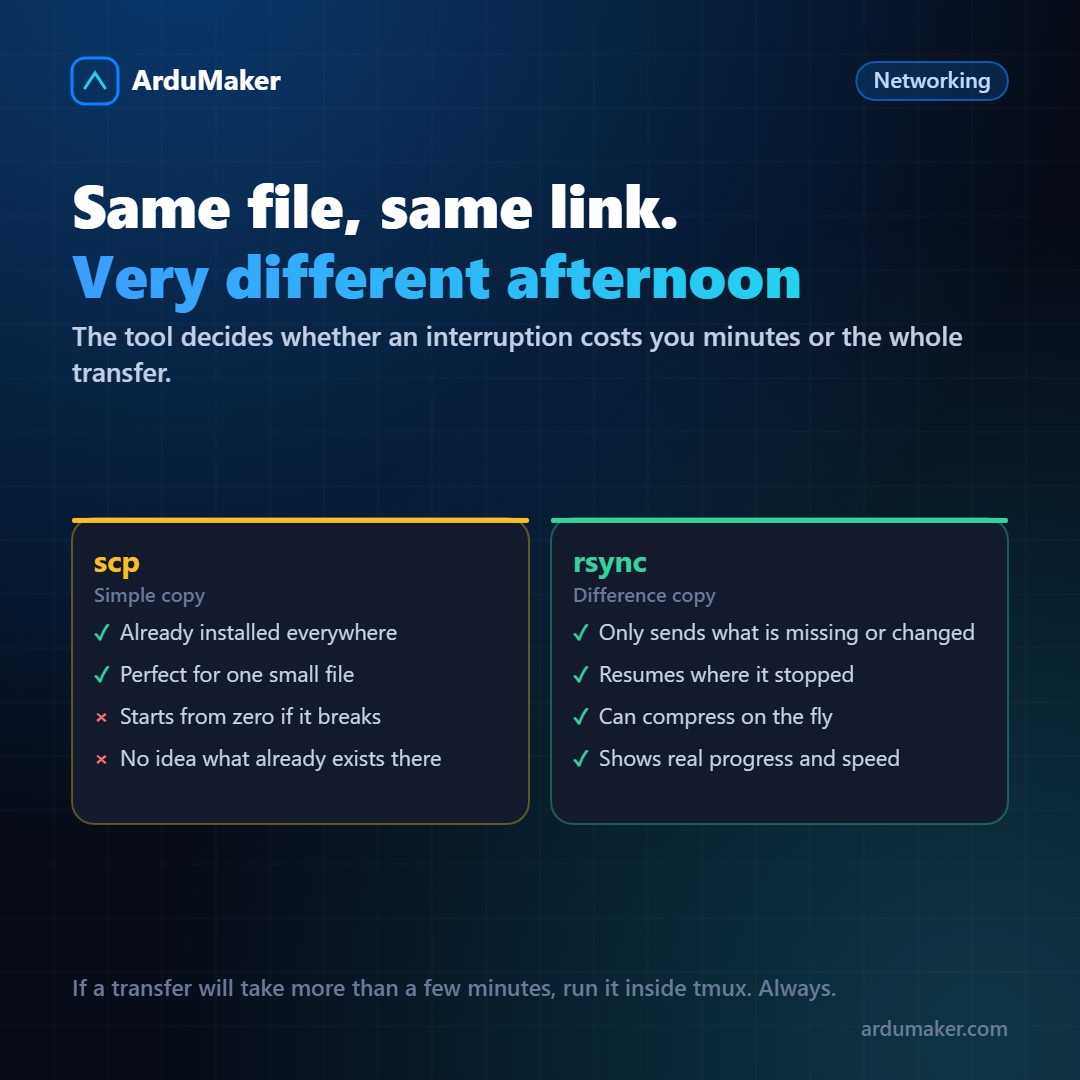
Copying a 200 MB file is no big deal. Copying 200 GB, or a hundred thousand small files, is another problem: interruptions appear, disk limits, and decisions that change the total time by a factor of three.
The difference between scp and rsync
scp copies. Period. If the connection is cut at 90%, you start from zero. If the file is already on the other side, it copies it anyway.
rsync compares before copying. It looks at what is on the destination and transfers only what is missing or changed. If it is cut, it resumes from where it left off.
rsync -avzP --partial origen/ servidor:/destino/
The flags, one by one:
- a (archive): preserves permissions, dates, and links, and goes down recursively.
- v (verbose): shows what it is doing.
- z: compresses during sending.
- P: shows progress and enables resuming partial files.
A detail that bites: the trailing slash on the source matters. With "origen/" it copies the contents of the folder; without the slash, it copies the entire folder inside the destination. It is the most frequent cause of "I ended up with a folder inside another folder".
When to compress and when not to
The compression flag seems free and it is not: it consumes CPU on both ends.
- It is worth it with text, code, logs, database dumps: they compress a lot.
- It is not worth it with already compressed files (video, images, zips): the CPU works to not reduce anything, and if the network is fast, compression becomes the bottleneck.
Rule of thumb: slow network and compressible data, compress. Fast network or already-compressed data, don't.
Many small files are another problem
Transferring one hundred thousand 10 KB files is much slower than a single 1 GB file, even if the total size is similar. Each file involves metadata, permissions, and a round trip.
The solution is to pack at the source and unpack at the destination, in a single pipeline:
tar czf - carpeta/ | ssh servidor "tar xzf - -C /destino"
This creates the package on the fly, sends it over SSH, and unpacks it on the other side, without writing an intermediate file. For trees of many small files, the difference is enormous.
Where the bottleneck really is
Before blaming the network, it's worth checking, because in half the cases it isn't the network:
- The disk. A mechanical disk runs around 100 to 150 MB/s in sequential read and much less with small files. If your network delivers more than that, the disk is the limit.
- The CPU. With compression enabled and a fast network, the processor can become the bottleneck. You can tell by watching CPU usage during the transfer.
- The network. Only then.
An experiment that clarifies the discussion: run the transfer without compression and compare. If it's the same speed or faster, compression was getting in the way.
Two habits that avoid suffering
Use tmux. Any transfer lasting more than a few minutes should run inside a tmux session. If your connection drops, the process continues on the server and you can reconnect to see it.
Check at the end. Comparing the size is not enough: a truncated transfer can match. Comparing the hash does.
sha256sum archivo.tar.gz # on both sides
For database dumps and anything you're going to need seriously, that step is worth the thirty seconds it takes.